Choose an AI SEO tool by the question you need answered: where a platform shows your site, what happens for selected questions, or what needs fixing on your pages. Those jobs require different evidence. A single “best tools” score can hide the differences.
This guide compares Google Search Console, Bing Webmaster Tools, Ahrefs Brand Radar, Semrush AI Visibility Toolkit, Screaming Frog SEO Spider and Peec AI. It focuses on search visibility and diagnosis. It does not compare AI writing assistants or every SEO product on the market.
We selected these examples to cover platform reports, broad answer datasets, chosen-question monitoring and site crawling. Inclusion means a product illustrates one of those jobs. It is not a finding that these six outperform the alternatives.
We reviewed official product documentation on 6 October 2026. The comparison describes documented capabilities and metric definitions; it is not a hands-on test of accuracy, usability or performance. SEO Informatica provides AI SEO services, and the selection advice below is our editorial judgment.
Use the tool explorer to filter by task and evidence, compare up to three options, and prepare a brief you can copy or download. The filters reflect the documented roles covered here. They do not assess every capability, rank the products or verify your account access.
Start with the question, then choose the evidence
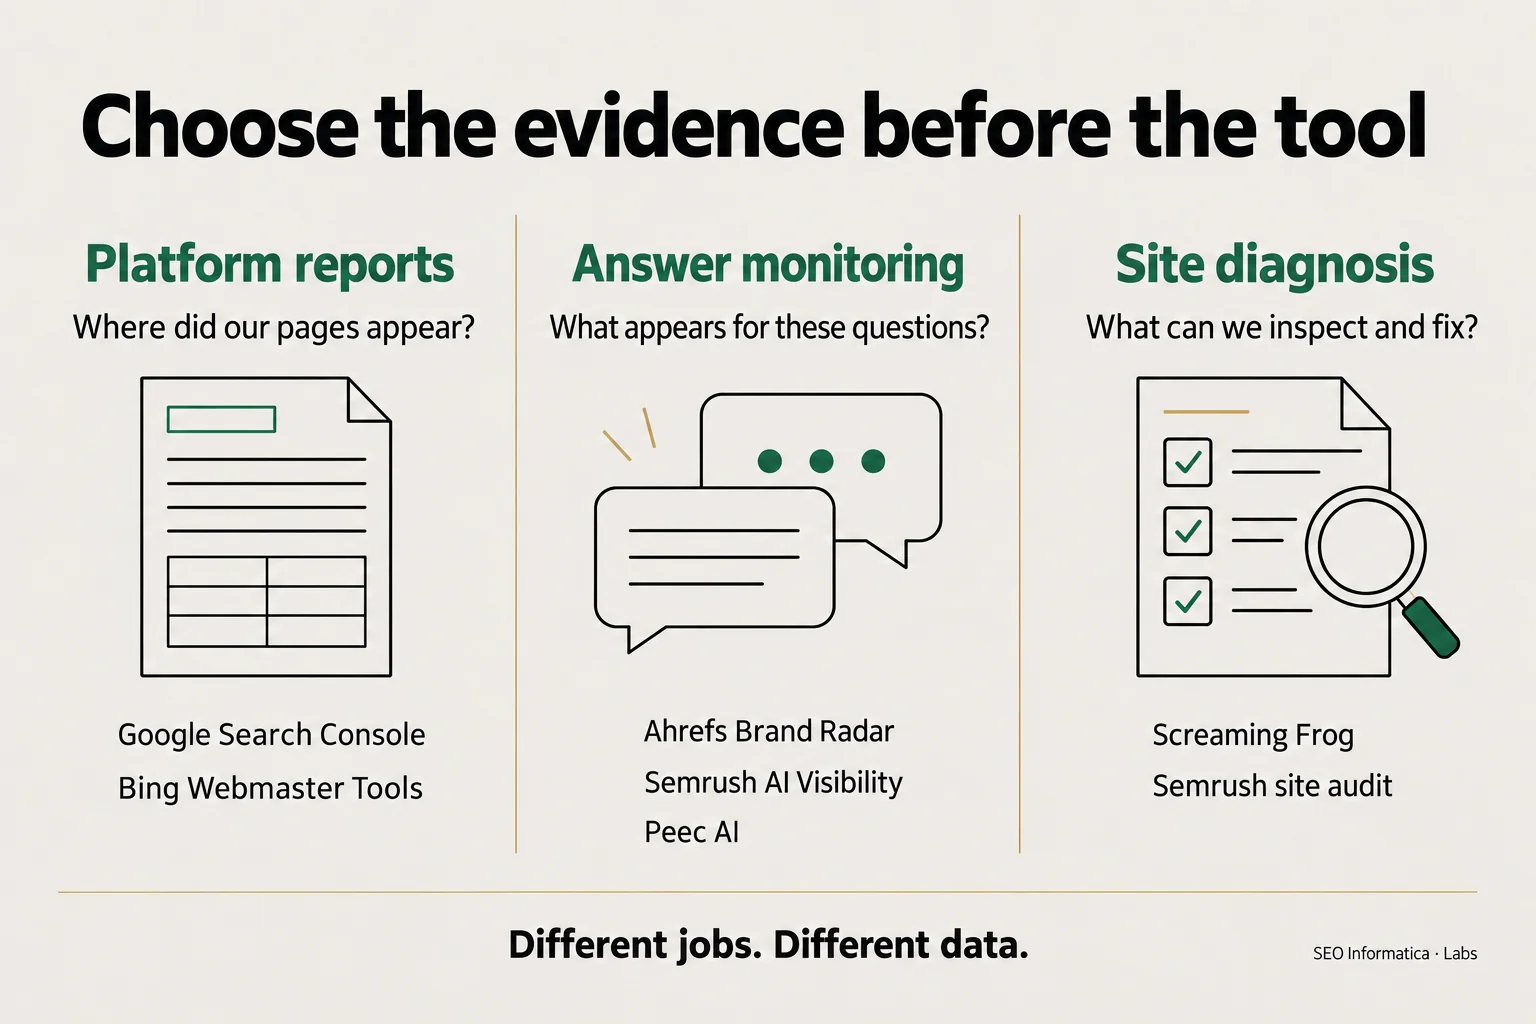
Open the tool selection infographic full size. The groups describe different jobs and data, not a ranking of products.
| Your question | Evidence to inspect | Options covered here |
|---|---|---|
| Where does Google show links to our pages in AI features? | Google’s own impression reporting | Search Console |
| Which pages do supported Microsoft AI experiences cite? | Microsoft’s citation reporting | Bing Webmaster Tools |
| Which topics and sources feature brands in a broad answer dataset? | A vendor’s collected or modelled dataset | Ahrefs Brand Radar, Semrush |
| What happens for the buyer questions we choose to monitor? | Repeated checks of a defined question set | Ahrefs custom prompts, Semrush prompt tracking, Peec |
| What technical or content issues can we inspect on our site? | Crawl findings and page-level review | Screaming Frog; Semrush’s audit component |
These are useful categories, not interchangeable products. An existing account may already answer the question. Identify what is missing before adding another subscription.
If your job is drafting, query grouping or reviewing content, distinguish the assistant doing the work from the source supplying facts. A fluent output does not establish current search demand or a correct page decision. Our AI SEO introduction explains that separate use of AI. This guide concentrates on the evidence needed to investigate visibility and pages.
Google Search Console: Google’s own visibility record
Search Console’s dedicated Generative AI performance report for Search includes AI Overviews and AI Mode impressions. It provides page, country, device and date breakdowns. An impression records a link shown to a user within the covered features. Google’s report documentation.
Use it to investigate which pages receive that exposure. It does not provide a complete transcript of buyer prompts or attribute qualified enquiries to a particular AI answer. The AI impressions are already included in overall Web reporting; adding the two totals would double-count them.
A missing report does not establish zero exposure. Also check exports carefully: Google says unavailable values displayed as ~ or - become zeros in downloaded data. Preserve that distinction in your working notes.
Use this when: you need Google’s own record for an owned site before interpreting a third-party visibility score. Availability in an individual account must still be checked.
Bing Webmaster Tools: Microsoft’s citation record
AI Performance reports citations to your content across supported Microsoft AI experiences, including Copilot and AI-generated Bing summaries. The June 2026 preview update adds topic and intent views, comparisons and Citation Share. Microsoft’s feature announcement.
Citation Share describes the site’s share of citations for a grounding query. It is not a traffic share or a content-quality grade, and the report does not reveal the competing domains behind that share. Microsoft also cautions that machine-generated topic classifications may be broad for specialist subjects.
Grounding queries describe retrieval phrases rather than exact buyer prompts. The report summarizes sampled citation activity, not every answer. Microsoft’s launch documentation.
Use this when: you need to inspect cited pages and recurring themes in Microsoft’s covered experiences. Investigate changes in the record before crediting a particular edit with causing them.
Ahrefs Brand Radar: explore an answer index or track chosen prompts
Brand Radar combines a pre-existing AI-answer index with separately configured custom-prompt tracking. The index uses questions associated with Ahrefs’ keyword data; it is not a census of private assistant conversations. Brand Radar overview.
That distinction changes how you use it. A broad dataset can suggest topics and sources to investigate. A saved custom-question set can support repeated monitoring of your chosen questions. Keep those datasets separate when comparing periods. Custom-prompt documentation.
Ahrefs distinguishes mentions, citations and pages found as sources. Its Impressions metric uses associated Google search volume, rather than observed people viewing the brand in an assistant. Its AI Share of Voice compares the brand’s share of those estimates with other tracked brands. Metric definitions.
Use this when: you want to explore a broad answer dataset and then investigate a defined set of questions. Check the current platform coverage and custom-tracking entitlements for the work you intend to do.
Semrush AI Visibility Toolkit: topic research, monitoring and diagnosis
Semrush combines broad AI visibility research, brand analysis, selected-prompt tracking and an AI site audit. Those components use different data sources, so the name of the report matters. Its documentation describes topic-volume estimates as modelled from multiple signals, including third-party interaction data. Data sources.
The toolkit’s metrics also need interpretation. AI Visibility is a vendor benchmark, while Monthly Audience estimates exposure. Neither is your website’s recorded visits or received enquiries. Metric definitions.
Use this when: you want to move between market-level topic investigation, selected-question monitoring and site diagnosis within a suite. Identify which component produced each finding and inspect the supporting answers or crawl evidence before acting.
Confirm current access and export limits for the intended account. A report you can view but cannot adequately inspect or retain may be less useful for an ongoing research process.
Screaming Frog SEO Spider: inspect what is on your website
SEO Spider is a crawler for inspecting site implementation. Its AI integrations can run configured prompts against page text, HTML or extracted elements and return results alongside crawl data. That can support classification or a first-pass content review. AI crawling documentation.
The resulting record concerns the pages and inputs the crawler processed. A favourable AI-generated assessment does not establish that Google indexed a page or that an assistant cited it. Review important findings against the underlying page.
When using external integrations, check where page data is sent. Licence requirements and model-provider charges are separate considerations; an existing ChatGPT subscription does not itself provide funded API access. Configuration documentation.
Use this when: you need to locate and verify technical or content issues, or check that an implemented fix appears in a fresh crawl. Pair it with platform reporting when the question concerns actual inclusion.
Peec AI: monitor selected questions and brand appearances
Peec’s Visibility measures how often a brand appears in its tracked answers. Its Share of Voice measures the brand’s share of mention counts against tracked competitors. Those measures describe the configured response sample. Visibility, Share of Voice.
Its Position metric concerns average mention order within answers where the brand appears. It is not a conventional search-results position. The product also distinguishes accessed sources from sources explicitly referenced in the final response. Position, source definitions.
Use this when: you have defined the questions and markets you want to monitor and need to inspect brand appearances and sources over time. Check the underlying answers, including whether a mention is accurate and whether it is a recommendation.
Similar metric names can conceal different measurements
Two examples matter when comparing reports:
| Label | Product meaning | Practical consequence |
|---|---|---|
| Impressions | Google: links shown in covered AI features. Ahrefs: estimates based on associated Google search volume. | Do not add them or treat them as equivalent audience counts. |
| Share of voice | Ahrefs: share of estimated impressions. Peec: share of tracked brand-mention counts. | Compare each metric within a consistent setup; do not turn the percentages into a cross-tool league table. |
These distinctions come from the official metric definitions linked above. They do not make one product inherently better. They tell you which conclusion its number can support.
The same discipline applies to a score labelled “visibility” or “authority.” Ask what it counts, which sample it covers, and what would change its denominator. A higher score is not automatically evidence of more buyers seeing your business.
Evaluate a tool with one task you can inspect
Before a trial or demonstration, write down the decision you need to make. Then request enough underlying evidence to assess it.
Download the plain-text evaluation worksheet. It includes blank fields and a hypothetical example with three questions, separate observations and a decision.
- Define the task. For example, identify which sources appear for a set of relevant consultancy-buying questions.
- Record the conditions. Keep the platform, location, language, dates, prompt set and collection method visible where the product exposes them.
- Inspect the output. Read the response and the cited page. Check brand identity, factual accuracy and whether a source was cited or merely retrieved.
- Check the metric. Record the numerator, denominator, weighting and deduplication behind the summary.
- Repeat comparably. Annotate changed prompts, models, competitors or product coverage. Treat unavailable runs separately from observed absence.
- Make the decision. Identify the action the evidence supports and the person who will carry it out.
If you compare tools, use equivalent inputs wherever possible and record the differences you cannot control. Agreement is not proof of accuracy, and disagreement is a reason to inspect the collection methods. Keep output quality, review effort and maintenance costs in the evaluation.
This is a proposed evaluation procedure. We have not run a comparative product trial for this guide.
A worked example: two dashboards, different questions
Consider a fictional payroll consultancy choosing how to monitor its service description. One candidate shows a market-level visibility score. Another exposes answers to selected questions. Their headline percentages might look comparable, but they could describe different samples, definitions and collection methods.
The useful first step is to ask whether both candidates can expose comparable selected-question records. If they cannot, document their different roles. A market research tool can still help find topics, while a chosen-question monitor may help inspect specific answers.
| Evaluation decision | What the fictional team records |
|---|---|
| Keep the input clear | Exact consultancy-buying questions, market, language, brand definition and planned runs. |
| Check the evidence | The complete answer, linked page and whether that page supports the description. A mention and a recommendation remain separate. |
| Retain differences | Different collection times, undisclosed model versions and unavailable records. Unknown does not become zero. |
| Decide whether it is useful | Can the reviewer inspect an issue and give a specific next action to the person who can resolve it? |
This is a hypothetical evaluation, not a product test or an accuracy result. Agreement between two dashboards would not prove both are right. A discrepancy would justify reading the underlying records before choosing a tool or changing the site.
Download the tool-trial brief and this hypothetical comparison, or prepare a selected-tool version in the explorer. Use the existing citation log for ongoing answer observations rather than inventing a new record for each product.
What should you verify before committing?
Ask for the exact product, plan and component that will perform your task. Check current platform and market coverage, question or crawl limits, source access, historical retention, exports, team access and the total commitment. Licence and model-provider requirements can be separate. The explorer marks your account access and commercial terms Unknown because a documentation review cannot establish them for you.
Then identify the work around the software: setup, human review, correction, integration and implementation. Record that effort during an actual trial. A quick first output can still require substantial checking, and a clear finding is useful only if someone can act on it.
If you cannot inspect enough evidence to answer your question, keep that as an unresolved requirement. It is a reason to ask for a demonstration or choose another approach, not a finding that the product is inaccurate.
What should a small team start with?
Our recommendation is to start with the platform reports and business records you can already access. Identify a question they cannot answer before choosing a specialist product.
For example, platform reports may establish that pages receive exposure, while a defined answer sample helps investigate how the firm is described. A crawler may then help inspect a suspected implementation issue. Each step has a purpose, and none requires treating a score as a complete diagnosis.
Software can supply evidence, suggest work or support a workflow. Confirm who will investigate, approve and implement changes. If that responsibility is the missing piece, compare the cost of software, advice and implementation and use the provider evaluation guide.
Keep visits and received enquiries alongside visibility records. If the terminology itself is unclear, start with what AI SEO means.